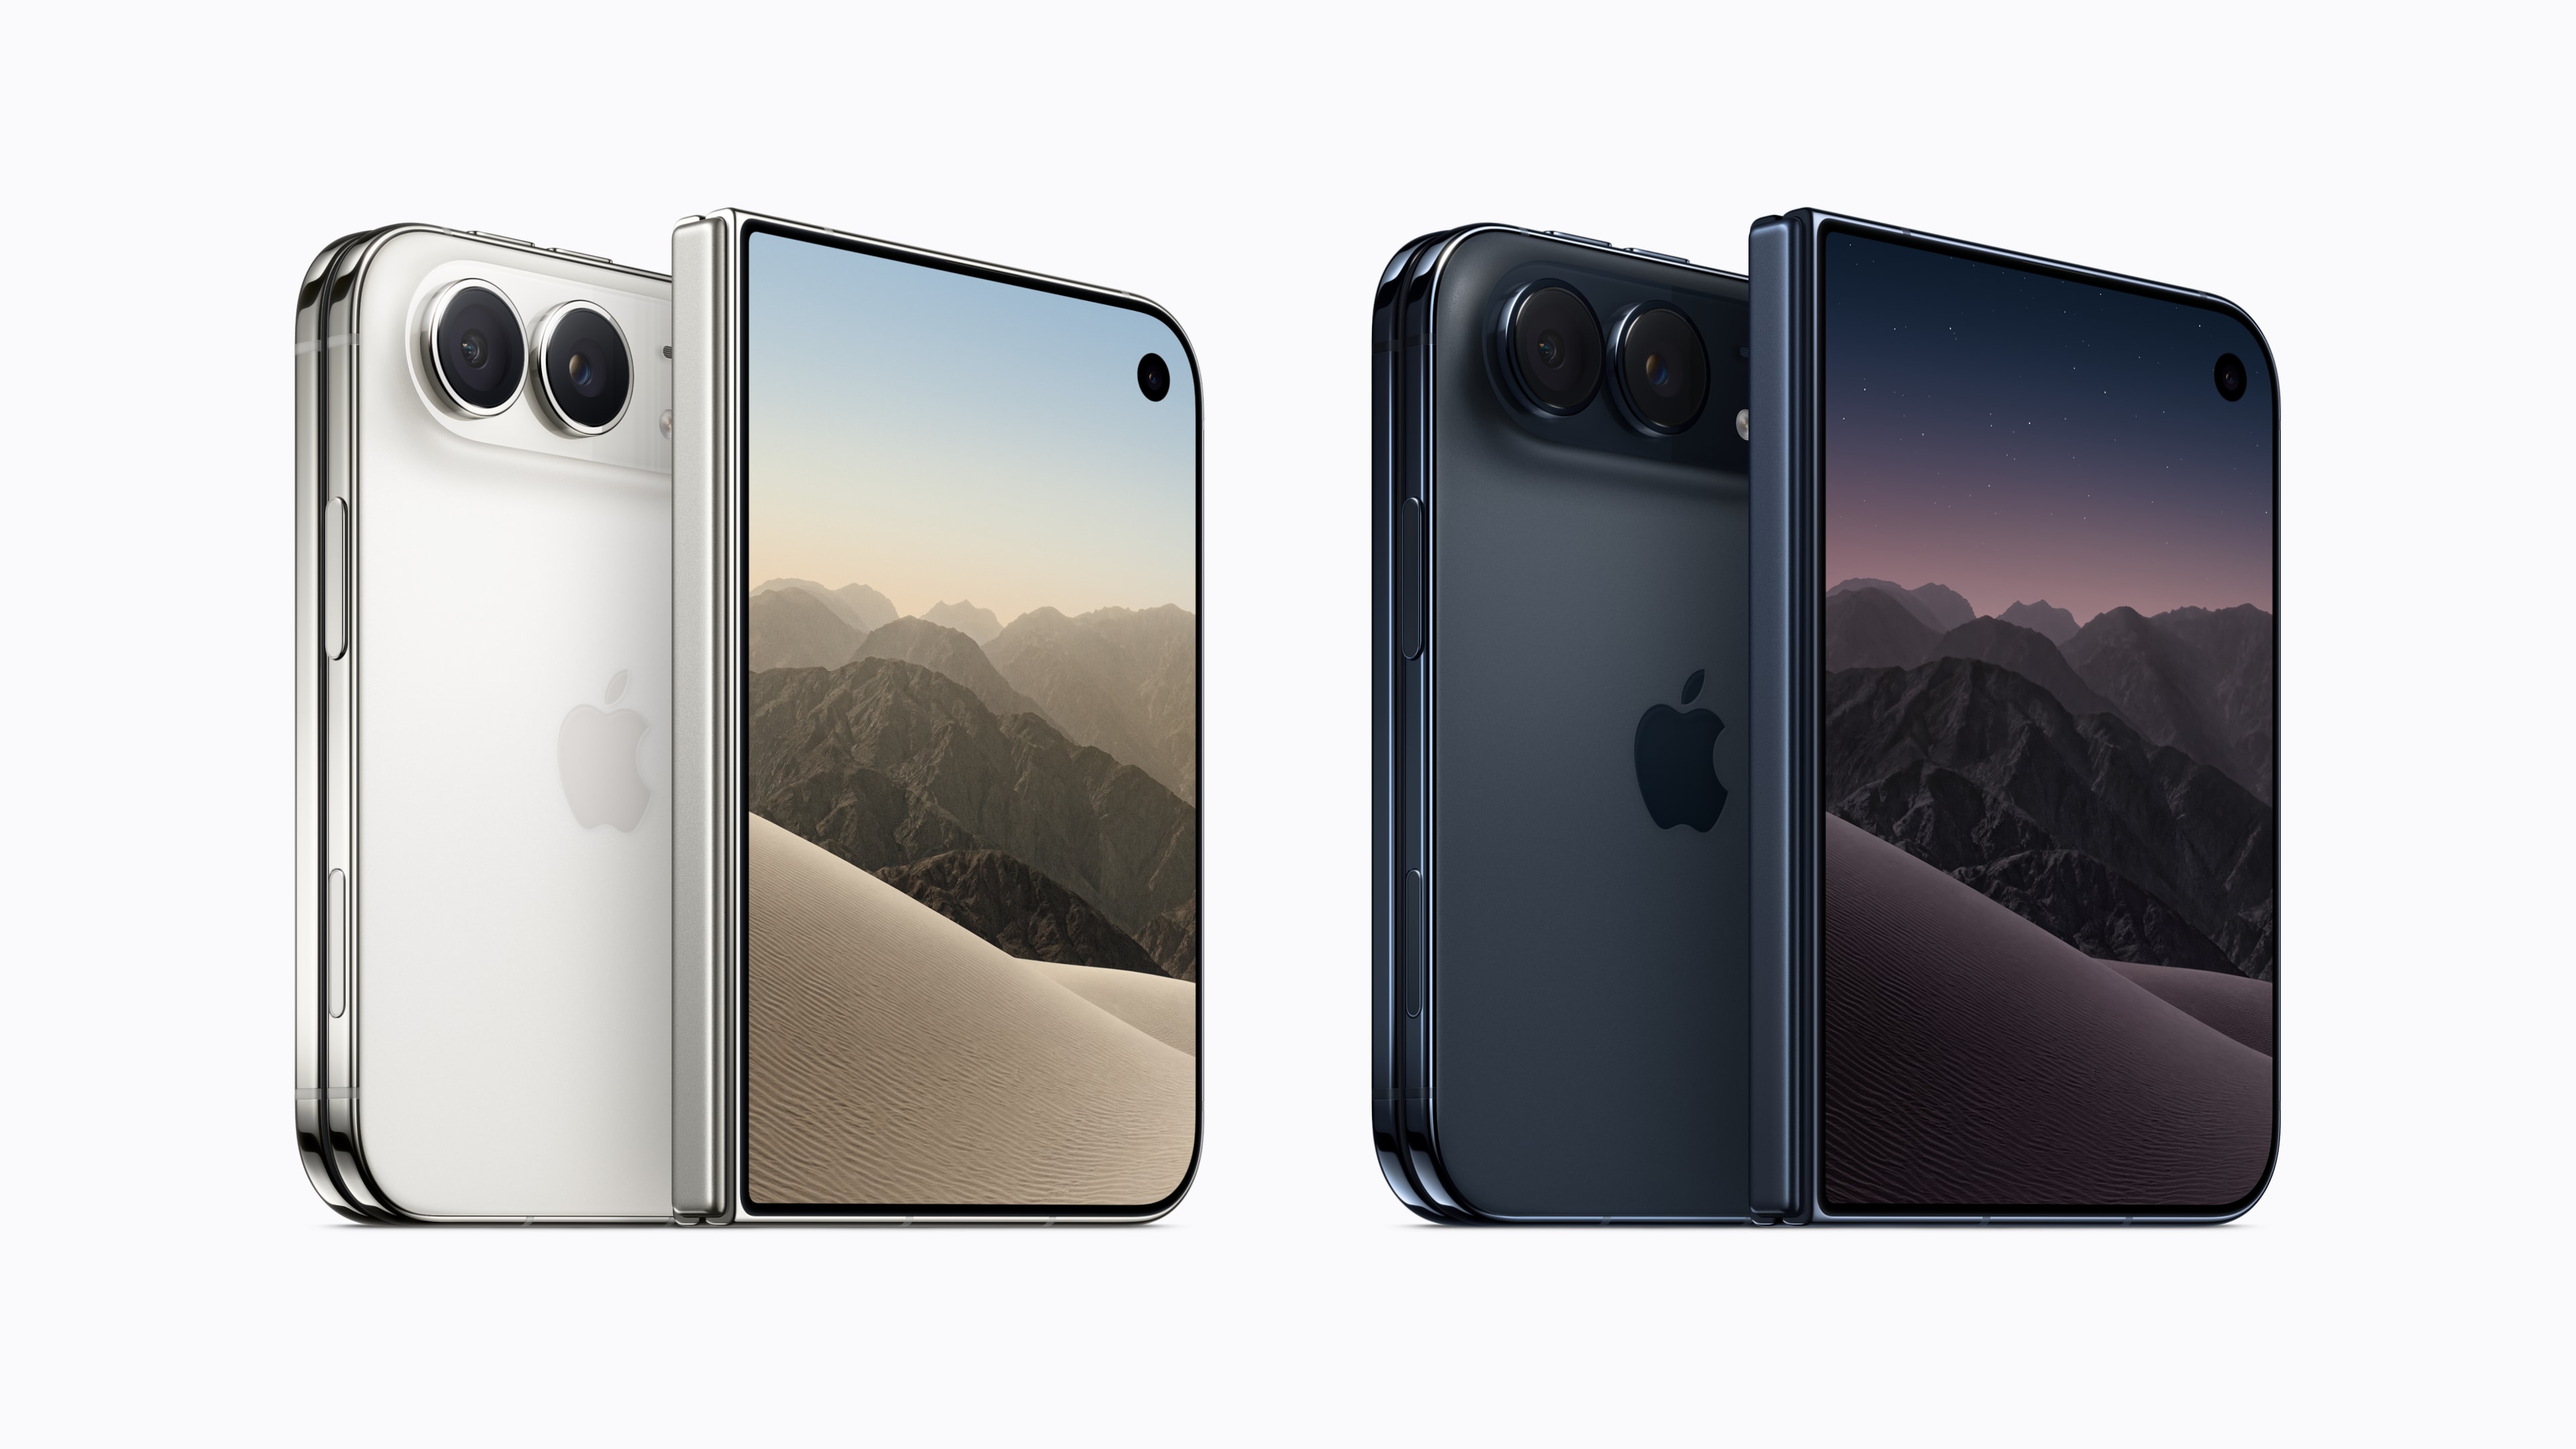
Apple's first foldable iPhone goes on sale from $1,999
3 min read
Research breakdown / Technology / 2 MIN READ
Running an AI assistant becomes expensive when a service sends it large amounts of work. Anthropic’s pitch for Claude Opus 5.5 is that developers can get more capable answers while spending less and waiting less time for them.
The company released the model on September 22, 2026, reporting improvements over Opus 5 in coding, computer-use tasks and writing. Those claims matter particularly to people using its API, the connection that lets their own software send requests to Claude and receive its responses.
For those users, charges are based on tokens, the chunks of text a model reads and writes. Opus 5.5’s listed price is $4 per million input tokens, down from $5, and $20 per million output tokens, down from $25. Those rates cover the material sent to the model and the reply it produces, with both falling 20%.
Anthropic’s broader claim is that typical workloads cost about 40% less to run, with output more than 30% faster. That workload figure describes the company’s estimate of running costs, rather than the reduction in the listed token rates. Reusing stored prompt material is also cheaper: reading from the prompt cache, which holds input for reuse, fell from $0.50 to $0.20 per million tokens.
Alongside those savings, Anthropic says Opus 5.5 performs at the level of Claude Fable 5.1 on most work. Fable is the company’s higher-capability tier. Outside evaluator METR described Opus 5.5 as an incremental improvement over Fable 5.1 on AI research-and-development tasks, and considered it unlikely to fully automate AI research by itself.
Comparing performance also requires checking how each model was run. Some public scoreboards gave Opus 5.5 an extra-high effort setting while a rival used a lower setting, so the comparison involved different levels of effort.
A further complication comes from Anthropic’s safety routing. The company says many cybersecurity requests go to Opus 4.8, while some biology and advanced AI-development requests go to Opus 5. It says these routes are disclosed and describes additional biology safeguards and a life-sciences verification program.
That means the model named on a service is not necessarily the one answering every request. For developers assessing the cheaper pricing and faster output, a useful test is to run their own workloads, check the resulting costs and responses, and confirm which model actually handled the work.
More on these ideas